---
license: other
license_name: qwen-research
license_link: LICENSE
base_model:
- Qwen/Qwen-Image-2.1
tags:
- gguf
- quantized
- comfyui
- qwen-image
- text-to-image
---
# Qwen-Image-2.1 DiT — GGUF (Q8_0 · Q6_K · Q4_K_M)
> **Not affiliated with, or endorsed by, Alibaba / Qwen.** Quantized redistribution of the
> [`Qwen/Qwen-Image-2.1`](https://huggingface.co/Qwen/Qwen-Image-2.1) diffusion transformer under the
> **Qwen Research License** (copy included as `LICENSE`). **Non-commercial use only.**
> [!IMPORTANT]
> **Loads in stock [city96/ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF) — no patch, no extra nodes.**
> These files carry `general.architecture = qwen_image`, so `UnetLoaderGGUF` recognises them directly
> (GGUFs without that field fail with `Unknown model architecture!`).
>
> **Text encoder:** our [Qwen-Image-2.1 Text Encoder GGUF](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-GGUF)
> works with this DiT, but it needs one extra node first —
> [ComfyUI-GGUF-Qwen3VL-TE](https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE) (stock ComfyUI-GGUF
> doesn't load Qwen3-VL text encoders yet). With a **safetensors** text encoder (bf16 / int8 / FP8 from the same
> repo family) nothing extra is needed.
## Made with a simple node
The sample / showcase images in this repo were generated with the technique behind **[ComfyUI-QwenImage-PhotoStyles](https://github.com/pottokao-dotcom/ComfyUI-QwenImage-PhotoStyles)** — a small ComfyUI node (17 photographic styles; one short prompt becomes a full styled prompt via the PE-T2I rewriter). If you're interested in how the images are made, the node and its recipe are there.
**Where are the prompts?** The node is applied *up front* as the **PE-T2I** step — you type one short line and it expands it into the full prompt. The exact short prompts live in that repo's **Gallery**: the line printed under each image there **is** the literal prompt (copy it verbatim), not a description of the picture.
## 📥 Files
| File | Size | For |
|---|---:|---|
| `qwen_image_2.1-Q8_0.gguf` | 7.69 GB | closest to bf16 |
| `qwen_image_2.1-Q6_K.gguf` | 6.00 GB | nearly identical to Q8_0 in our test |
| `qwen_image_2.1-Q4_K_M.gguf` | 4.34 GB | **recommended** — smallest; small detail changes vs Q8_0 |
Put one in `ComfyUI/models/diffusion_models/` (or `models/unet/`) and load it with **`UnetLoaderGGUF`**.
Needs ComfyUI **0.36.0 or newer** (for `TextEncodeQwenImage21`).
## 🖼️ Showcase

Warm Documentary | 
Candid B&W Street | 
Vivid Everyday Color |

Black Fury | 
Geometry of Light | 
Frozen Film Still |

Deadpan Large-Format | 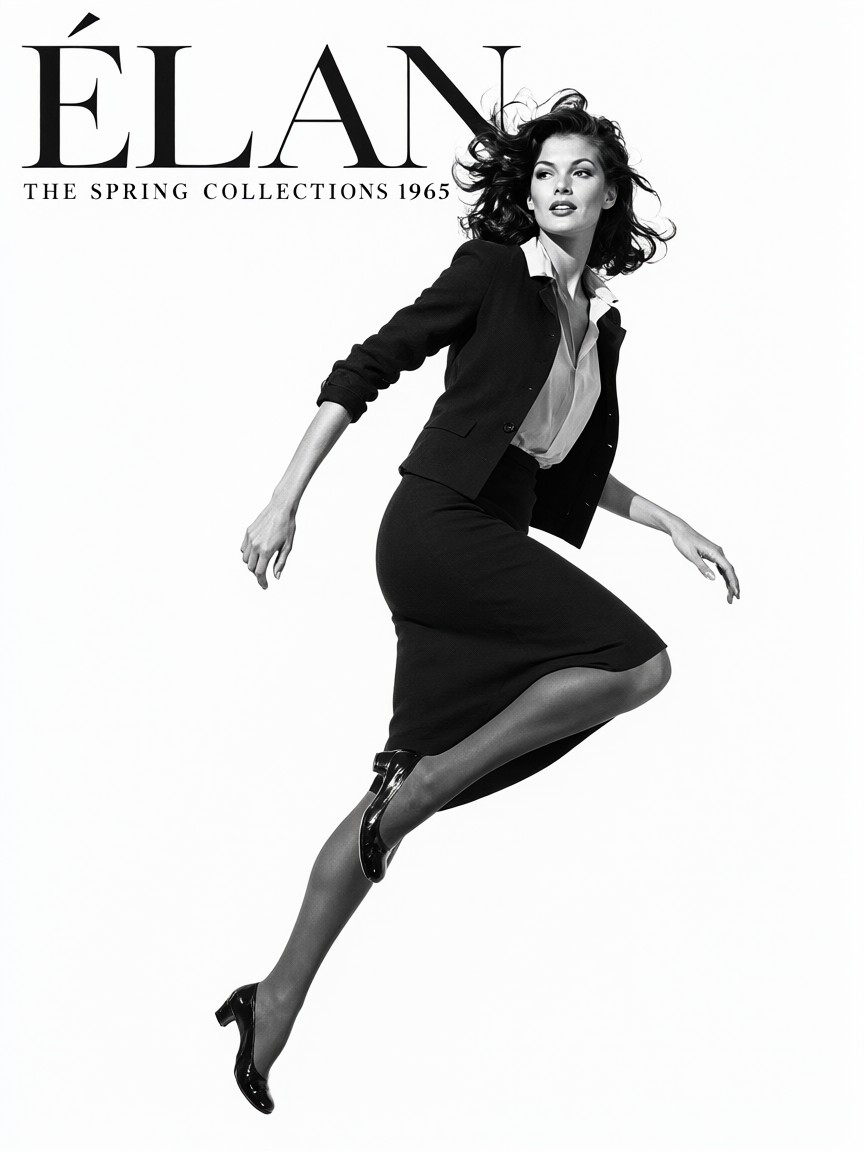
White Leap | 
Corner Elegance |

Raw B&W Fashion | 
Color Behind Glass | 
High-Contrast Reportage |

Lyrical Landscape | 
Hyper Chic East | 
Street in the Mirror |

Plain Portrait | 
Melancholy B&W | 
Fairytale Giants |

Cold Power | 
Cold Power | 
Hyper Chic East |

Fairytale Giants | 
Hyper Chic East | 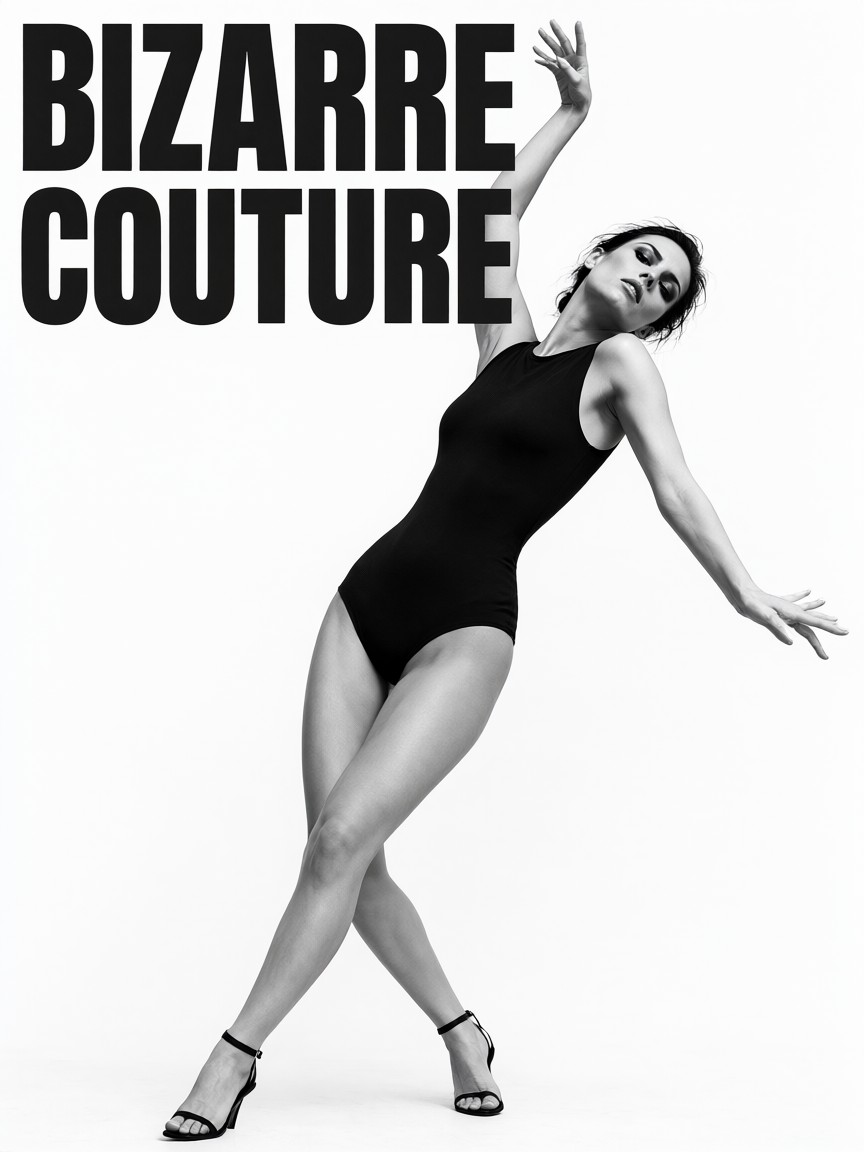
White Leap |
**This is what Q4_K_M across the board looks like** — every image above was made with:
| Part | File |
|---|---|
| PE-T2I rewriter | [`pe_t2i_heretic-Q4_K_M.gguf`](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic-GGUF) |
| Text encoder | [`qwen3vl_8b_heretic-Q4_K_M.gguf`](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-GGUF) + f16 mmproj |
| DiT | [`qwen_image_2.1-Q4_K_M.gguf`](https://huggingface.co/pottokao/Qwen-Image-2.1-DiT-GGUF) |
| VAE | `qwen_image_2.1_vae_bf16.safetensors` (official) |
AI-generated. Style homage only — not affiliated with or endorsed by the photographers.
## 🍱 All-GGUF Qwen-Image-2.1
The whole pipeline can run on GGUF — useful on Macs and smaller GPUs:
| Part | File | Where | Loader |
|---|---|---|---|
| Prompt rewriter *(optional)* | `pe_t2i_heretic-Q4_K_M.gguf` + `system_prompt.txt` | [PE-T2I Heretic GGUF](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic-GGUF) | llama.cpp / LLM node |
| Text encoder | `qwen3vl_8b_heretic-Q4_K_M.gguf` + `mmproj-…-f16.gguf` | [Text Encoder Heretic GGUF](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-GGUF) | `CLIPLoaderGGUF` + [patch node](https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE) (until ComfyUI-GGUF supports Qwen3-VL) |
| **DiT** | `qwen_image_2.1-Q4_K_M.gguf` (or Q6_K / Q8_0) | **this repo** | `UnetLoaderGGUF` — stock |
| VAE | `qwen_image_2.1_vae_bf16.safetensors` (official) | — | `VAELoader` |
Prefer no patch at all? Use a safetensors text encoder instead (e.g.
[bf16](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-GGUF) or
[int8-convrot](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-int8-convrot)) with the stock `CLIPLoader`.
## ⚙️ Recommended sampler settings
**25 steps**, euler / simple. For images with text (signs, posters, labels), switch cfg partway through with two
`KSamplerAdvanced` nodes — the first 15 steps at **cfg 1** lock in composition and materials, the last 10 at
**cfg 3** with a negative prompt redraw the lettering:
| | `add_noise` | `steps` | `cfg` | `start_at_step` | `end_at_step` | `return_with_leftover_noise` |
|---|---|---:|---:|---:|---:|---|
| 1st | enable | 25 | 1.0 | 0 | **12–17** | enable |
| 2nd | disable | 25 | 3.0 | **12–17** | 25 | disable |
Example negative prompt: `oversaturated, overexposed, gibberish text`. Without text, a single `KSampler` at cfg 1.0 is fine.
## Quantization
Standard ComfyUI-GGUF image-model rules — **no per-layer sensitivity scan**:
| Tensors | Q4_K_M | Q6_K | Q8_0 |
|---|---|---|---|
| `img_in`, `txt_in`, `time_text_embed`, `norm_out`, `proj_out`, `modulation` | BF16 (kept) | BF16 (kept) | BF16 (kept) |
| `attn.to_v` (×32 blocks) | **Q6_K** | Q6_K | Q8_0 |
| `attn.to_q / to_k / to_out`, `img_mlp.gate_up / out` | Q4_K | Q6_K | Q8_0 |
| norms | F32 | F32 | F32 |
## How it was made (reproducible)
Converted from the official bf16 weights (ComfyUI layout, 265 tensors) with ComfyUI-GGUF's own tooling.
Neither its `convert.py` nor its patched llama.cpp knew Qwen-Image, so both got a small addition — the
patches are in [`tools/`](tools):
- `tools/convert-qwen_image.patch` — adds a `qwen_image` template to `convert.py` (7 lines)
- `tools/llama.cpp-b3962-qwen_image.patch` — ComfyUI-GGUF's `lcpp.patch` plus a `qwen_image` architecture
and its keep-in-BF16 list
```bash
# ComfyUI-GGUF's tools/ with tools/convert-qwen_image.patch applied
python tools/convert.py --src qwen_image_2.1_bf16.safetensors --dst qwen_image_2.1-BF16.gguf
# llama.cpp at tag b3962 with tools/llama.cpp-b3962-qwen_image.patch applied
llama-quantize qwen_image_2.1-BF16.gguf qwen_image_2.1-Q4_K_M.gguf Q4_K_M # also Q6_K, Q8_0
```
## Verified
On ComfyUI 0.36.0 + ComfyUI-GGUF `6ea2651` (NVIDIA GPU):
- **Stock loader** — ComfyUI started with only ComfyUI-GGUF enabled (every other custom node disabled):
all three files load through `UnetLoaderGGUF` with no compatibility-mode warning and generate normally.
In that test (one prompt, one seed), they give near-identical images; Q6_K and Q8_0 are almost indistinguishable, Q4_K_M
differs in small details. Rendered Chinese text (shop sign and a handwritten price menu) came out correct
in all three.
- **All-GGUF pipeline** — Q4_K_M together with the Q4_K_M GGUF text encoder and the GGUF prompt rewriter.
Not tested on a Mac. Not tested: a numeric quality comparison against bf16.


