---
license: apache-2.0
base_model:
- pottokao/Qwen-Image-2.1-Text-Encoder-Heretic
tags:
- quantized
- fp8
- gguf
- comfyui
- qwen-image
- abliterated
- text-encoder
---
# Qwen-Image-2.1 Text Encoder (Heretic) — GGUF · FP8 · bf16
> [!IMPORTANT]
> **Got `got input of size [1, 512, 12288]` with the GGUF? It's fixed.**
> The GGUF files were fine all along — ComfyUI-GGUF just didn't load the Qwen3-VL vision tower.
> Install the add-on node **[ComfyUI-GGUF-Qwen3VL-TE](https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE)**,
> make sure the `mmproj` file sits next to the GGUF, restart ComfyUI. No need to re-download anything.
> The same patch also fixes `Unknown model architecture!` for Qwen-Image-2.1 **DiT** GGUFs — so the whole
> pipeline can run on GGUF.
## Made with a simple node
The sample / showcase images in this repo were generated with the technique behind **[ComfyUI-QwenImage-PhotoStyles](https://github.com/pottokao-dotcom/ComfyUI-QwenImage-PhotoStyles)** — a small ComfyUI node (17 photographic styles; one short prompt becomes a full styled prompt via the PE-T2I rewriter). If you're interested in how the images are made, the node and its recipe are there.
## 📥 Which file should I use?
| Your setup | File(s) | Size | Loader |
|---|---|---:|---|
| **Smallest** (GGUF) | `qwen3vl_8b_heretic-Q4_K_M.gguf` **+** `mmproj-qwen3vl_8b_heretic-f16.gguf` | 5.0 + 1.2 GB | `CLIPLoaderGGUF` + [add-on node](https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE) |
| **NVIDIA GPU**, no extra nodes | `qwen3vl_8b_fp8_heretic.safetensors` | 9.3 GB | stock `CLIPLoader` |
| **Mac / non-CUDA**, no extra nodes | `qwen3vl_8b_bf16_heretic.safetensors` | 17.5 GB | stock `CLIPLoader` |
All three are in **this repo**. Every loader uses **type `qwen_image`** and feeds `TextEncodeQwenImage21`.
## ⚙️ Recommended sampler settings
Qwen-Image-2.1 is a full (non-distilled) model. **Use 25 steps** — more steps don't make text sharper
and start to burn the highlights.
- **No text in the image:** plain `KSampler`, **cfg 1.0** (fastest, softest look; the negative prompt is ignored at cfg 1).
- **Text in the image (signs, labels, posters):** switch cfg **partway through** — the first ½–⅔ of the steps
at **cfg 1** lock in composition and materials, the rest at **cfg 3** with a negative prompt redraws the
lettering. You get cfg 1's look *and* cfg 3's readable text, in one pass with one seed.
In ComfyUI that's two chained `KSamplerAdvanced` nodes (same model, seed and steps):
| | `add_noise` | `steps` | `cfg` | `start_at_step` | `end_at_step` | `return_with_leftover_noise` |
|---|---|---:|---:|---:|---:|---|
| 1st | enable | 25 | 1.0 | 0 | **12–17** | enable |
| 2nd | disable | 25 | 3.0 | **12–17** | 25 | disable |
Split later (17) keeps more of the cfg 1 look; split earlier (12) gives crisper text.
Example negative prompt: `oversaturated, overexposed, gibberish text`.
## 🍱 All-GGUF Qwen-Image-2.1
| Part | Where | Loader |
|---|---|---|
| Prompt rewriter *(optional)* | [PE-T2I Heretic GGUF](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic-GGUF) | llama.cpp / LLM node |
| Text encoder | **this repo** — Q4_K_M + mmproj | `CLIPLoaderGGUF` + [patch node](https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE) |
| DiT | [Qwen-Image-2.1 DiT GGUF](https://huggingface.co/pottokao/Qwen-Image-2.1-DiT-GGUF) — Q8_0 / Q6_K / Q4_K_M | `UnetLoaderGGUF` — **stock, no patch** |
| VAE | official `qwen_image_2.1_vae_bf16.safetensors` | `VAELoader` |
## 🖼️ Showcase

Warm Documentary | 
Candid B&W Street | 
Vivid Everyday Color |

Black Fury | 
Geometry of Light | 
Frozen Film Still |

Deadpan Large-Format | 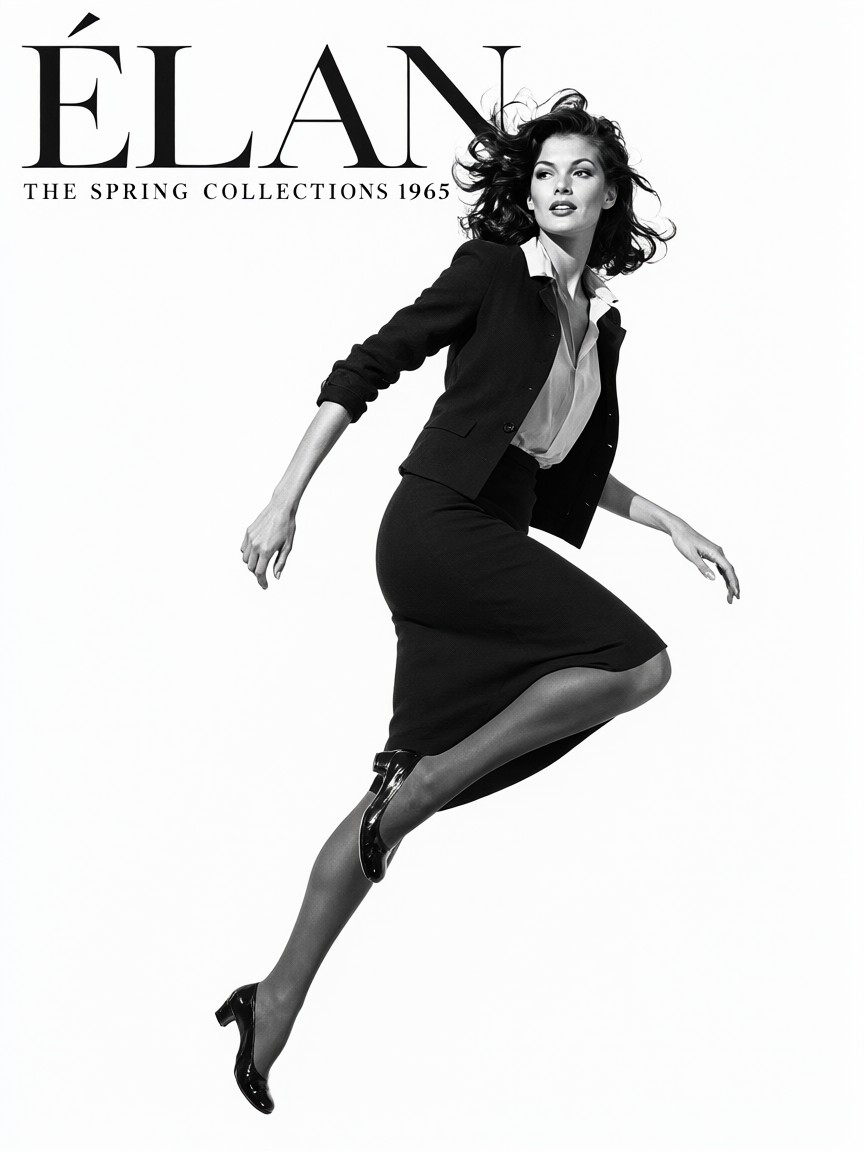
White Leap | 
Corner Elegance |

Raw B&W Fashion | 
Color Behind Glass | 
High-Contrast Reportage |

Lyrical Landscape | 
Hyper Chic East | 
Street in the Mirror |

Plain Portrait | 
Melancholy B&W | 
Fairytale Giants |

Cold Power | 
Cold Power | 
Hyper Chic East |

Fairytale Giants | 
Hyper Chic East | 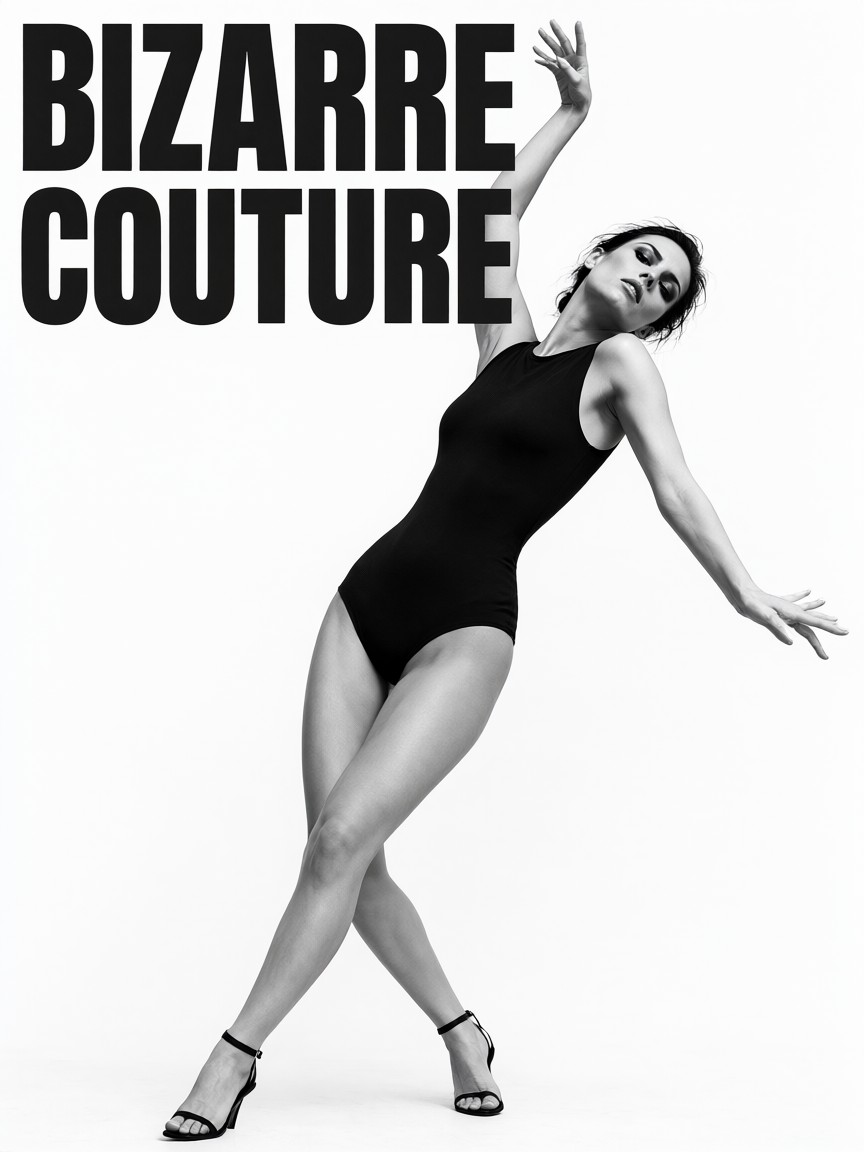
White Leap |
**This is what Q4_K_M across the board looks like** — every image above was made with:
| Part | File |
|---|---|
| PE-T2I rewriter | [`pe_t2i_heretic-Q4_K_M.gguf`](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic-GGUF) |
| Text encoder | [`qwen3vl_8b_heretic-Q4_K_M.gguf`](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-GGUF) + f16 mmproj |
| DiT | [`qwen_image_2.1-Q4_K_M.gguf`](https://huggingface.co/pottokao/Qwen-Image-2.1-DiT-GGUF) |
| VAE | `qwen_image_2.1_vae_bf16.safetensors` (official) |
AI-generated. Style homage only — not affiliated with or endorsed by the photographers.
## GGUF in ComfyUI — 3 steps
1. **Install two custom nodes** into `ComfyUI/custom_nodes/`:
| Node | What it does |
|---|---|
| [city96/ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF) | the GGUF loaders (`CLIPLoaderGGUF`, `UnetLoaderGGUF`) — also in ComfyUI Manager |
| [pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE](https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE) | temporary patch for Qwen-Image-2.1 until ComfyUI-GGUF supports it — manual install only |
```bash
cd ComfyUI/custom_nodes
git clone https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE
```
No git? On the GitHub page click **Code → Download ZIP**, unzip it into `ComfyUI/custom_nodes/`.
New to custom nodes: [official guide](https://docs.comfy.org/installation/install_custom_node).
The patch fixes both errors: the text encoder's `[1, 512, 12288]`, and
`Unknown model architecture!` when a Qwen-Image-2.1 **DiT** GGUF has no architecture
metadata (e.g. [unsloth](https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF) / [leejet](https://huggingface.co/leejet/Qwen-Image-2.1-GGUF) builds).
2. **Put both files in `ComfyUI/models/text_encoders/`**
- `qwen3vl_8b_heretic-Q4_K_M.gguf`
- `mmproj-qwen3vl_8b_heretic-f16.gguf` ← the vision tower (**required** — also used for image editing)
**Don't rename either file** — the vision tower is matched by name. If it's missing, the add-on
stops with a `Missing vision tower` error telling you which file to download.
3. **Restart ComfyUI**, then `CLIPLoaderGGUF` → type **`qwen_image`** → `TextEncodeQwenImage21` → the rest of the official workflow.
The console should show `[GGUF-Qwen3VL-TE] added 351 Qwen3-VL vision tensors from mmproj.`
Verified 2026-09-23 on ComfyUI 0.36.0 + ComfyUI-GGUF `6ea2651` (NVIDIA GPU): **text-to-image and
reference-image editing** both work and match the bf16 encoder's output for the same seed up to Q4
quantization noise. Not tested on a Mac.
What the patch changes, and why: see [the bottom of this page](#what-the-patch-handles).
## Files in this repo
| File | Size | Use for |
|---|---:|---|
| `qwen3vl_8b_heretic-Q4_K_M.gguf` | 5.03 GB | ComfyUI via `CLIPLoaderGGUF` + add-on · llama.cpp |
| `qwen3vl_8b_heretic-Q6_K.gguf` | 6.88 GB | higher quality — same loader (`CLIPLoaderGGUF` + add-on + mmproj) |
| `qwen3vl_8b_heretic-Q8_0.gguf` | 8.71 GB | near-lossless — same loader (for spare VRAM) |
| `mmproj-qwen3vl_8b_heretic-f16.gguf` | 1.16 GB | vision tower — **required** next to the GGUF |
| `qwen3vl_8b_fp8_heretic.safetensors` | 9.34 GB | ComfyUI via stock `CLIPLoader` (NVIDIA GPU) |
| `qwen3vl_8b_bf16_heretic.safetensors` | 17.53 GB | ComfyUI via stock `CLIPLoader` (any device, incl. Mac) — full precision |
### Other formats of the same model
| Repo | Format | Size | Note |
|---|---|---:|---|
| [`…-Heretic`](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic) | bf16 | 17.5 GB | HF `transformers` shards (+ the same bf16 single file) |
| [`…-int8-convrot`](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-int8-convrot) | INT8 convrot | 9.35 GB | official template default format, CUDA |
| [`…-W4A8`](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-W4A8) | W4A8 | 6.31 GB | CUDA |
| [`…-NVFP4`](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic-NVFP4) | NVFP4 | 6.31 GB | Blackwell GPUs |
## Ablation (inherited from the bf16 source)
| | Refusals | KL divergence |
|---|---:|---:|
| Stock Qwen-Image-2.1 text encoder | 100/100 | 0 *(by definition)* |
| **This family** | **5/100** | **0.0220** |
Produced with [Heretic](https://github.com/p-e-w/heretic) directional ablation
(`o_proj` + `down_proj`), 200 trials / 60 startup trials, knee point of the Pareto
front. Independently re-checked on the bf16 source: **0/20** refusals, **4/4** benign
questions answered correctly. Full methodology in the
[bf16 repo](https://huggingface.co/pottokao/Qwen-Image-2.1-Text-Encoder-Heretic).
## Format details
**GGUF:** Q4_K_M language model, vision tower as a separate f16 `mmproj`.
**FP8:** self-quantized `float8_e4m3fn` (Comfy-Org doesn't ship an FP8 encoder):
| Layers | Count | Precision |
|---|---:|---|
| FFN + attention + embed/lm_head (all 2-D weights) | 254 | **FP8** `e4m3fn` |
| Vision tower | 351 tensors | **bf16 — untouched** |
| norms / biases | — | bf16 |
Remapped to the ComfyUI key layout (`model.layers.…`, no `language_model.` prefix).
Requires a ComfyUI build with `QwenImage21` support (0.36.0 or newer).
## 🎨 Also for Qwen-Image-2.1: the prompt rewriters (Heretic)
Qwen-Image-2.1 ships two **prompt rewriters** — small LLMs that expand a short request into
the detailed prompt the model was trained on. Both are available refusal-ablated, and both have
**GGUF builds that run anywhere llama.cpp runs (Mac included)**:
| Rewriter | What it does | Builds |
|---|---|---|
| **PE-T2I** (text-to-image) | one line in any language → detailed English prompt + aspect ratio | [GGUF](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic-GGUF) · [NVFP4](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic-NVFP4) · [bf16](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic) |
| **PE-I2I** (image editing) | vague edit instruction + input image(s) → precise editing prompt | [GGUF + mmproj](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-I2I-Heretic-GGUF) |
A short request goes in; one JSON line comes out (real output of the PE-T2I GGUF, trimmed):
```text
in: 雨夜的東京小巷,一隻流浪狗,粗粒黑白街拍風格
out: {"rewritten_prompt": "A vertical nighttime street photograph in a gritty grainy black-and-white street style shows a
narrow, rain-soaked urban alley with a stray dog standing in the lower foreground. The scene is
composed with strong depth: dark building walls and utility poles frame the left and right sides,
while the wet pavement stretches into a softly blurred background. … (2,137 characters)",
"wh_ratio": "2:3"}
```
**Showcase** — generated with the **NVFP4** builds through the full pipeline (PE-T2I rewriter →
Qwen-Image-2.1 text encoder → DiT), each from a one-line prompt, one seed per image, no retouching.
Also shown in the [PE-T2I NVFP4 repo](https://huggingface.co/pottokao/Qwen-Image-2.1-PE-T2I-Heretic-NVFP4).
## What the patch handles
[ComfyUI-GGUF-Qwen3VL-TE](https://github.com/pottokao-dotcom/ComfyUI-GGUF-Qwen3VL-TE) changes nothing on
disk — it only adjusts how ComfyUI-GGUF loads Qwen-Image-2.1 files, in memory, at load time.
**1. Text encoder — `[1, 512, 12288]`**
```
RuntimeError: Given normalized_shape=[4096], expected input with shape [*, 4096],
but got input of size [1, 512, 12288]
```
ComfyUI-GGUF loads the `mmproj` vision tower only for `qwen2vl`, not `qwen3vl`. Without it, ComfyUI
doesn't recognise the encoder as Qwen3-VL, builds the wrong model, and gets 12288-wide hidden states
instead of 4096. The patch loads the matching `mmproj-*.gguf` from the same folder and renames its
tensors to ComfyUI's Qwen3-VL layout (`model.visual.*`). The vision tower is then really used —
reference images for editing go through it.
**2. DiT — `Unknown model architecture!`**
```
ValueError: This model is not currently supported - (Unknown model architecture!)
```
A DiT GGUF without `general.architecture` metadata (stable-diffusion.cpp convention, e.g. unsloth /
leejet) is identified by its tensor names, and ComfyUI-GGUF's list has no Qwen-Image entry. The patch
recognises Qwen-Image-2.1 by `img_in`, `txt_in.in_layer` and `txt_in.text_norm` and loads it as
`qwen_image`. DiT GGUFs that already carry the metadata (e.g. Abiray's) are unaffected.
Once ComfyUI-GGUF handles either case itself, that part of the patch detects it and does nothing.
---
> **Not affiliated with, or endorsed by, Alibaba / Qwen.** Community derivative
> (refusal-ablated) of [`Qwen/Qwen3-VL-8B-Instruct`](https://huggingface.co/Qwen/Qwen3-VL-8B-Instruct)
> — the model Qwen-Image-2.1 uses, unmodified, as its text encoder. Qwen releases that
> model under **Apache-2.0**, so this derivative is redistributed under Apache-2.0
> (see `LICENSE` and `NOTICE`).


